parakeet-ctc-0.6b-es
DownloadableAccurate and optimized Spanish English transcriptions with punctuation and word timestamps.
Speech Recognition: Parakeet CTC 0.6b Spanish English Code Switch Model
Description
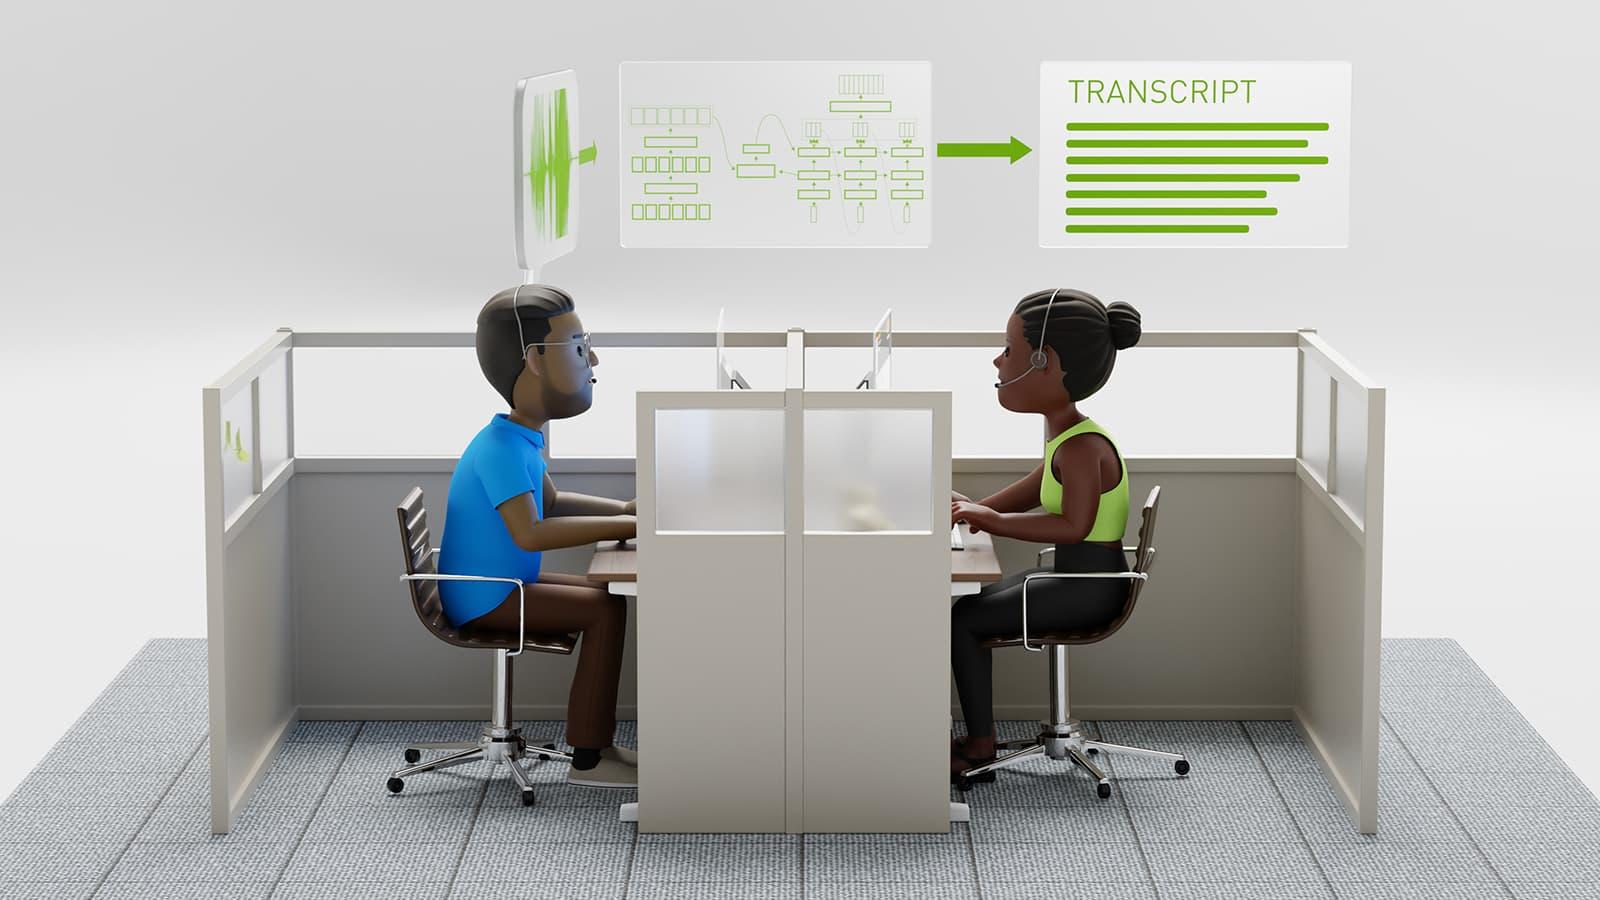
NVIDIA Parakeet-CTC-0.6B is a 600M parameter model trained on ASR Set with over 28k hours of Spanish (es-US) and English (en-US) speech. The model transcribes speech in Spanish and English, in upper case and lower case alphabets, along with punctuations (period, comma, and question mark), spaces, and apostrophes.
This model is ready for commercial use.
Terms of use
GOVERNING TERMS: This trial is governed by the NVIDIA API Trial Terms of Service (found at https://assets.ngc.nvidia.com/products/api-catalog/legal/NVIDIA%20API%20Trial%20Terms%20of%20Service.pdf).
References
- Fast Conformer with Linearly Scalable Attention for Efficient Speech Recognition
- Fast-Conformer-CTC Model
- Conformer: Convolution-augmented Transformer for Speech Recognition
Model Architecture
Architecture Type: Parakeet-CTC (also known as FastConformer-CTC) [1], [2] which is an optimized version of Conformer model [3] with 8x depthwise-separable convolutional downsampling with CTC loss
Network Architecture: Parakeet-CTC-XXL-0.6B
Input
Input Type(s): Audio Input Format(s): wav Input Parameters: 1-Dimension Other Properties Related to Input: Maximum Length in seconds specific to GPU Memory, No Pre-Processing Needed, Mono channel is required
Output
Output Type(s): Transcription for what was spoken in input speech
Output Type(s): Text
Output Format: String (in Spanish and English)
Output Parameters: 1-Dimension
Other Properties Related to Output: No Maximum Character Length, Does not handle special characters
Supported Operating System(s):
- Linux
Model Version
Parakeet-CTC-XL-unified-0.6b_spe1024_es-en-US_3.0
Training & Evaluation
Training Dataset
Data Collection Method by dataset
- Human
Labeling Method by dataset
- Human
Properties:
This model is trained on over 28,000 hours of Spanish (es-US) and English (en-US) speech, comprised of a dynamic blend of public and internal proprietary and customer datasets normalized to have upper-cased, lower-cased, punctuated, and spoken forms in text.
Evaluation Dataset
Data Collection Method by dataset
- Human
Labeling Method by dataset
- Human
Properties: A dynamic blend of public and internal proprietary and customer datasets normalized to have upper-cased, lower-cased, punctuated, and spoken forms in text.
Inference
Engine: Triton
Test Hardware:
- NVIDIA A10
- NVIDIA A100
- NVIDIA A30
- NVIDIA H100
- NVIDIA Jetson Orin
- NVIDIA L4
- NVIDIA L40
- NVIDIA Turing T4
- NVIDIA Volta V100
Ethical Considerations (For NVIDIA Models Only):
NVIDIA believes Trustworthy AI is a shared responsibility and we have established policies and practices to enable development for a wide array of AI applications. When downloaded or used in accordance with our terms of service, developers should work with their internal model team to ensure this model meets requirements for the relevant industry and use case and addresses unforeseen product misuse. For more detailed information on ethical considerations for this model, please see the Model Card++ Explainability, Bias, Safety & Security, and Privacy Subcards. Please report security vulnerabilities or NVIDIA AI Concerns here.