cosmos3-nano
DownloadableFree EndpointGenerates physics-aware videos from text prompts or an image prompt for physical AI development.
Cosmos 3: Omnimodal World Models for Physical AI
Model Collection | Code | White Paper | Website
NVIDIA Cosmos™ is a world foundation model platform designed to accelerate the development of Physical AI by enabling machines to understand, simulate, and interact with the physical world across robotics, autonomous driving, and smart space environments, including industrial and factory-scale applications.
Model Overview: Cosmos3-Nano
Description
Cosmos3 is a collection of omnimodal world models capable of generating dynamic, high-quality video, image, audio, and action commands from combinations of text, image, video, and action trajectory inputs. It serves as a foundational building block for a broad range of Physical AI applications and research spanning world understanding, world generation, simulation, and embodied policy learning.
This model is ready for commercial and non-commercial use.
Model Developer: NVIDIA
Model Versions
-
Cosmos3-Nano:
- Given multimodal inputs including text, images, video, audio, and action trajectories, generate coherent text, images, video, audio, and action outputs for multimodal understanding, world simulation, future prediction, action reasoning, and Physical AI applications.
-
Cosmos3-Super:
- Given multimodal inputs including text, images, video, audio, and action trajectories, generate coherent text, images, video, audio, and action outputs for multimodal understanding, world simulation, future prediction, action reasoning, and Physical AI applications.
-
Cosmos3-Nano-Policy-DROID:
- Given language instructions and visual observations from the DROID robot platform, generate robot action trajectories for manipulation and control tasks.
-
Cosmos3-Super-Image2Video:
- Given one or more input images and optional text instructions, generate temporally coherent video sequences that are consistent with the provided visual content.
-
Cosmos3-Super-Text2Image:
- Given text input, generate high-fidelity images that are consistent with the provided description.
License
This model is released under the OpenMDW1.1
The model is not designed or tested by NVIDIA for use in any system or application where the use of or failure of such system or application developed with the model could result in injury, death, or catastrophic damage. NVIDIA is not liable to any party, in whole or in part, for any claims or damages arising from those uses. Any system or application developed with the model must include sufficient safety and redundancy features and comply with applicable legal and regulatory standards and requirements.
Deployment Geography
Global
Use Case
Physical AI: Encompassing robotics, autonomous vehicles (AV), and smart space environments, including industrial and factory-scale applications.
Release Date
Hugging Face 05/31/2026 via https://huggingface.co/collections/nvidia/cosmos3
GitHub 05/31/2026 via https://github.com/nvidia-cosmos/cosmos
Model Architecture
Architecture Type: Transformer
Network Architecture: Mixture-of-Transformers (MoT)
Cosmos3 is an Omni-modal foundation model built on a Mixture-of-Transformers (MoT) architecture consisting of two complementary transformer towers: an autoregressive transformer for discrete token generation and a diffusion transformer for continuous multimodal generation. During inference, text is generated through standard next-token autoregressive decoding, while non-text modalities, such as images, video, audio, and actions, are synthesized through iterative denoising. This unified architecture enables Cosmos3 to model heterogeneous modalities within a single framework while preserving generation mechanisms best suited to each modality.
This model was developed based on: Cosmos Framework
Number of trainable model parameters:
- Cosmos3-Nano: 16B
- Cosmos3-Super: 64B
- Cosmos3-Nano-Policy-Droid: 16B
- Cosmos3-Super-Image2Video: 64B
- Cosmos3-Super-Text2Image: 64B
Input/Output Specifications
- Generator Input
- Input Type(s): Text, Image, Video (with audio or without audio), Action Trajectory
- Input Format(s):
- Text: String
- Image: jpg, png, jpeg, webp
- Video (with or without audio): mp4
- Action: json (1D list)
- Input Parameters:
- Text: One-dimensional (1D)
- Image: Two-dimensional (2D)
- Video: Three-dimensional (3D)
- Audio: One-dimensional (1D)
- Action trajectory: One-dimensional (1D)
- Other Properties Related to Input:
- For video inputs, we accept various resolutions, including 720p, 480p, and 256p.
- When using input video with audio muxed into the video MP4 file, the audio should have 2 channels (stereo) and a 48 kHz sample rate.
- **Image and video inputs are RGB color (8 bits per channel, sRGB color space); grayscale inputs are not supported.
- **Action input is a per-frame sequence of robot/agent state or control values (e.g., joint positions, gripper state, camera pose). The full input is a 2D array shaped (T, D), where T is the number of frames and D is the embodiment-specific dimensionality listed below.
- Input action is only supported for compatible embodiments, including general camera motion (9D), autonomous vehicle (9D), egocentric motion (57D), single Franka Panda arm with RobotiQ gripper (10D), dual Franka Panda arm with RobotiQ gripper (20D), Agibot (29D), UR (10D), Google robot (10D), WidowX 250 (10D), UMI (9D).
- Input Size and Length limits:
- Text: 4096 tokens
- Image: 256p, 480p, and 720p resolution at one of these aspect ratios (16:9, 4:3, 1:1, 3:4, 9:16)
- Video: 256p, 480p, and 720p resolution at one of these aspect ratios (16:9, 4:3, 1:1, 3:4, 9:16). Max number of frames = 5.
- Audio: Max 0.5 second
- Action: 16 – 400 video frames
- Generator Output
- Output Type(s): Image, video, audio, action, text
- Output Format(s):
- Image: JPG
- Video: MP4
- Audio: Advanced Audio Coding (AAC) stream (muxed within the MP4)
- Action: 1D list (.json)
- Text: string
- Output Parameters:
- Image: Two-dimensional (2D)
- Video: Three-dimensional (3D)
- Audio: One-dimensional (1D)
- Action: One-dimensional (1D)
- Text: One-dimensional (1D)
- Other Properties Related to Output:
- The generated video is an MP4 file, with the resolution, frame rate, and duration specified in the input. The generated audio is encoded in AAC format, muxed into the video MP4 file with 2 channels (stereo) and a 48 kHz sample rate.
- Video generation supports durations from 5 to 400 frames, with 189 frames as the default generation duration.
- The generated action is only supported for compatible embodiments, including general camera motion (9D), autonomous vehicle (9D), egocentric motion (57D), single Franka Panda arm with RobotiQ gripper (10D), dual Franka Panda arm with RobotiQ gripper (20D), Agibot (29D), UR (10D), Google robot (10D), WidowX 250 (10D), UMI (9D).
- Audio: 48kHz stereo AAC stream muxed into video mp4
- Video: mp4 at the FPS specified in input
- Image: JPEG
- Reasoner Input
- Input Type(s): Text, Text+Image, Text+Video
- Input Format(s):
- Text: String
- Image: jpg, png, jpeg, webp
- Video: mp4
- Input Parameters:
- Text: One-dimensional (1D)
- Image: Two-dimensional (2D)
- Video: Three-dimensional (3D)
- Other Properties Related to Input:
- Video inputs are recommended at a frame rate of 4 fps.
- Long-context inputs supported up to 256K tokens.
- Input Size and Length limits:
- Text: Up to 256K tokens (context window).
- Image: Standard input image formats; passed as file or URL.
- Video: mp4 at the recommended 4 fps.
- Reasoner Output
- Output Type(s): Text
- Output Format(s):
- Text: string
- Output Parameters:
- Text: One-dimensional (1D)
- Other Properties Related to Output:
- Default
max_tokens=4096+is recommended for reasoning outputs; longer outputs may be requested. - Reasoning outputs may include structured chain-of-thought, 2D/3D point localization, and bounding-box coordinates for vision-based tasks.
- Default
The video content visualizes the input text description as a short animated scene, capturing key elements within the specified time constraints.
Our AI models are designed and/or optimized to run on NVIDIA GPU-accelerated systems. By leveraging NVIDIA's hardware (e.g. GPU cores) and software frameworks (e.g., CUDA libraries), the model achieves faster training and inference times compared to CPU-only solutions.
Software Integration
Runtime Engine(s):
Supported Hardware Microarchitecture Compatibility:
- NVIDIA Ampere
- NVIDIA Blackwell
- NVIDIA Hopper
Operating System(s):
- Linux (We have not tested on other operating systems.)
Note: Only BF16 precision is tested. Other precisions like FP4, FP8, and FP16 are not officially supported.
The integration of foundation and fine-tuned models into AI systems requires additional testing using use-case-specific data to ensure safe and effective deployment. Following the V-model methodology, iterative testing and validation at both unit and system levels are essential to mitigate risks, meet technical and functional requirements, and ensure compliance with safety and ethical standards before deployment.
Training, Testing, and Evaluation Datasets
Dataset Overview
Total Size: 1.3B data points Total Number of Datasets: 393 dataset entries Dataset partition: Training [100%], Testing [N/A — evaluation benchmarks used separately], Validation [N/A — evaluation benchmarks used separately] Time period for training data collection: 2024–2026 Time period for testing data collection: N/A (standard public benchmarks) Time period for validation data collection: N/A (standard public benchmarks)
Raw data from internal and external sources is transformed into training-ready data through multiple stages of curation, filtering, and quality review. Data acquisition spans diverse multimodal sources — robotics, autonomous driving, industrial environments, indoor and outdoor scenes, varied lighting and weather conditions, camera viewpoints, object categories, and human activities — to broaden coverage across Physical AI operating environments. Automated filtering pipelines remove corrupted, duplicate, low-quality, and restricted content. Metadata analysis, heuristic rules, and model-assisted classifiers are applied during preprocessing to flag anomalous distributions and low-diversity subsets. Human review supplements automated filtering for selected datasets, benchmark construction, and targeted quality analysis. Datasets are balanced across modalities and task categories — visual reasoning, text-to-image, text-to-video, image-to-video, audio generation, video transfer, action-conditioned generation, and action command generation — to reduce overrepresentation of narrow domains. Synthetic and simulation-based augmentation supplements coverage of rare physical interactions and edge-case scenarios. Deduplication and provenance tracking are applied across the corpus. The resulting processed data is converted into model-ready tokenized or encoded representations through modality-specific preprocessors before training begins.
Training datasets passed through multiple layers of automated and manual safeguards designed to reduce the presence of harmful or policy-violating content across categories including weapons and weapons-related instructional content, criminal planning, child sexual abuse material (CSAM), non-consensual intimate imagery (NCII), sexual content involving minors, harassment, hate speech, profanity, threats and incitement to violence, self-harm or suicide-related content, and graphic violence. Data sources are reviewed for licensing compatibility, provenance, and alignment with internal data governance and safety policies before admission into training corpora. Automated filtering pipelines combine multiple detection strategies: hash-matching against known CSAM and NCII reference databases; classifier-based moderation models trained for explicit sexual content, hate speech, violence, weapons imagery, and other restricted categories; keyword and regex-based screening for criminal-planning, threats, and self-harm phrases in text data; metadata and provenance heuristics for source-level risk signals; and embedding-based anomaly detection to surface samples that fall outside expected distributions. Human review and targeted audits supplement automated filtering for selected datasets, benchmark construction, and safety-sensitive evaluation. For multimodal Physical AI data (robotics, autonomous driving, industrial scenes), additional filtering targets invalid action trajectories, physically implausible interactions, and unsafe control sequences. Synthetic and simulation-generated data are evaluated through internal validation before inclusion. Benchmark evaluations and red-team testing are applied post-training to surface remaining safety gaps across world generation, reasoning, audio, and action tasks. No large-scale data-filtering process can guarantee complete removal of all harmful content; residual risks may remain, particularly in rare edge cases or open-world deployment settings. Ongoing monitoring and dataset review continue post-release.
- For more information about the datasets used to train this model, please see the Public Summary of Training Content
Data Modality and Training Data Size
| Modality | Reasoning Data Sample Count | Generation Data Sample Count |
|---|---|---|
| Text | 22M | Not Applicable |
| Image | 19M | 767M |
| Video | 1M | 348M |
| Audio | Not Applicable | 139M |
| Action | Not Applicable | 7M |
Data Collection Method by dataset
- Hybrid: Automatic/Sensors, Synthetic, Automated
Labeling Method by dataset
- Hybrid: Human, Automated
Properties: The training, testing, and evaluation datasets consist of diverse multimodal video, image, audio, action, synthetic, and sensor-conditioned data sourced from NVIDIA-owned data and publicly available, commercially permissive datasets. These datasets are curated to exclude known restricted content and to support building an Omni model that learns to generate and reason about dynamic physical environments across world reasoning and generation tasks.
Public Datasets
| Dataset | Samples |
|---|---|
| OpenImage | 1.2M |
| Coyo700M | 100M |
| YouTube Video | 340M |
| UMI | 4.5M |
Private Datasets
| Dataset | Samples |
|---|---|
| Egocentric | 7M |
| Nexar | 0.6M |
| AgiBot | 0.2M |
| HOI | 0.3M |
Synthetic Datasets
| Dataset | Samples |
|---|---|
| synthetic images generated using HiDream-I1 | 15M |
| synthetic images generated using Qwen-Image-2512 | 14M |
| synthetic captions generated using Qwen3-VL | 1115M |
Benchmarks
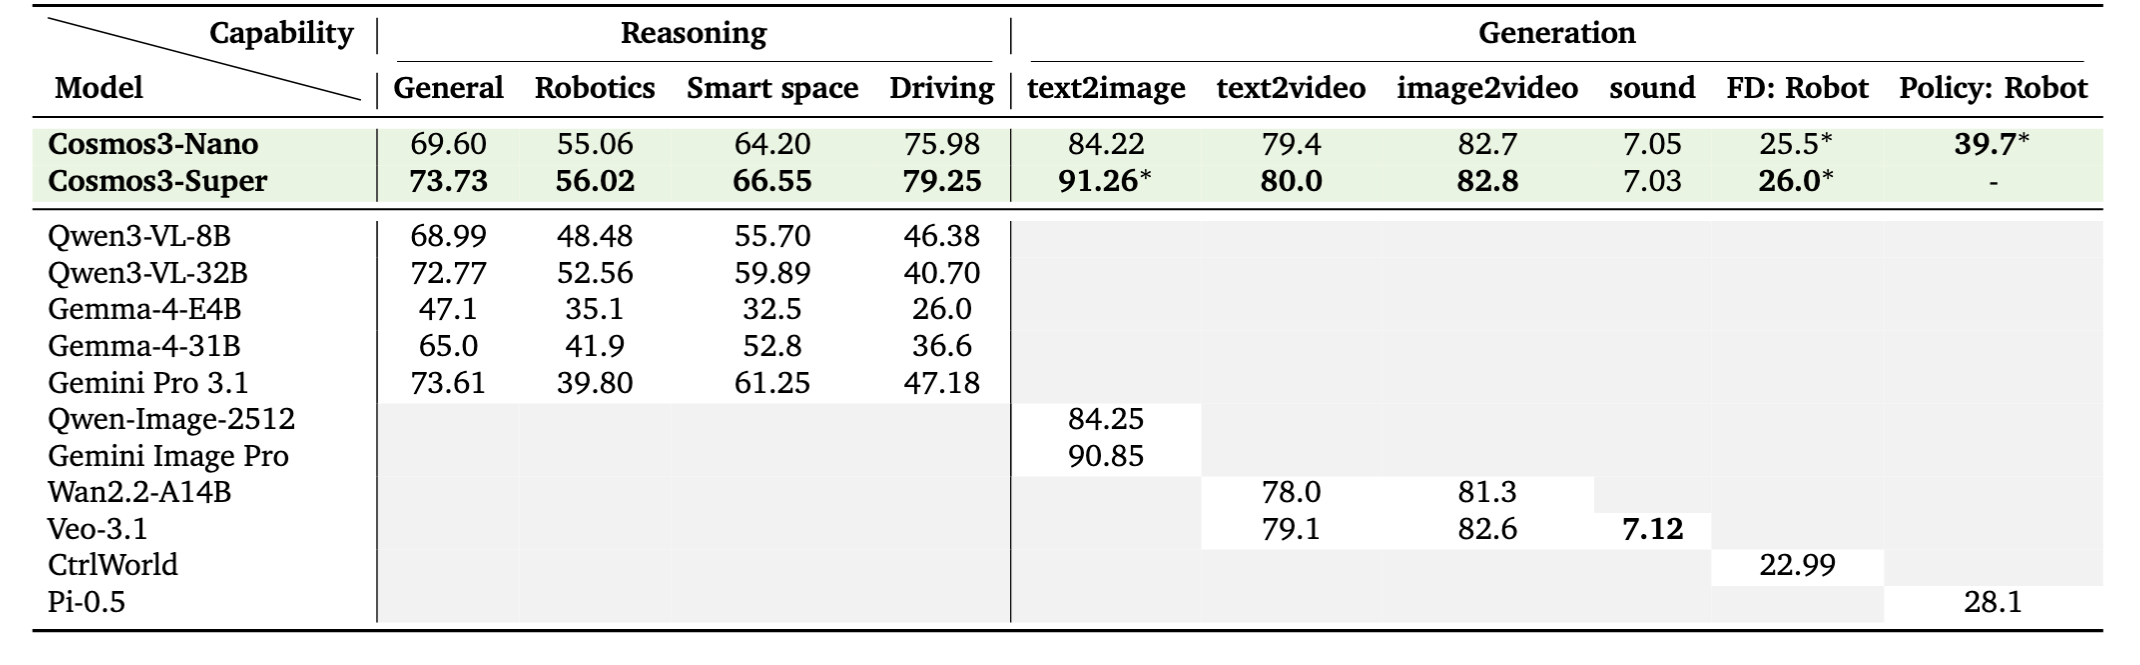
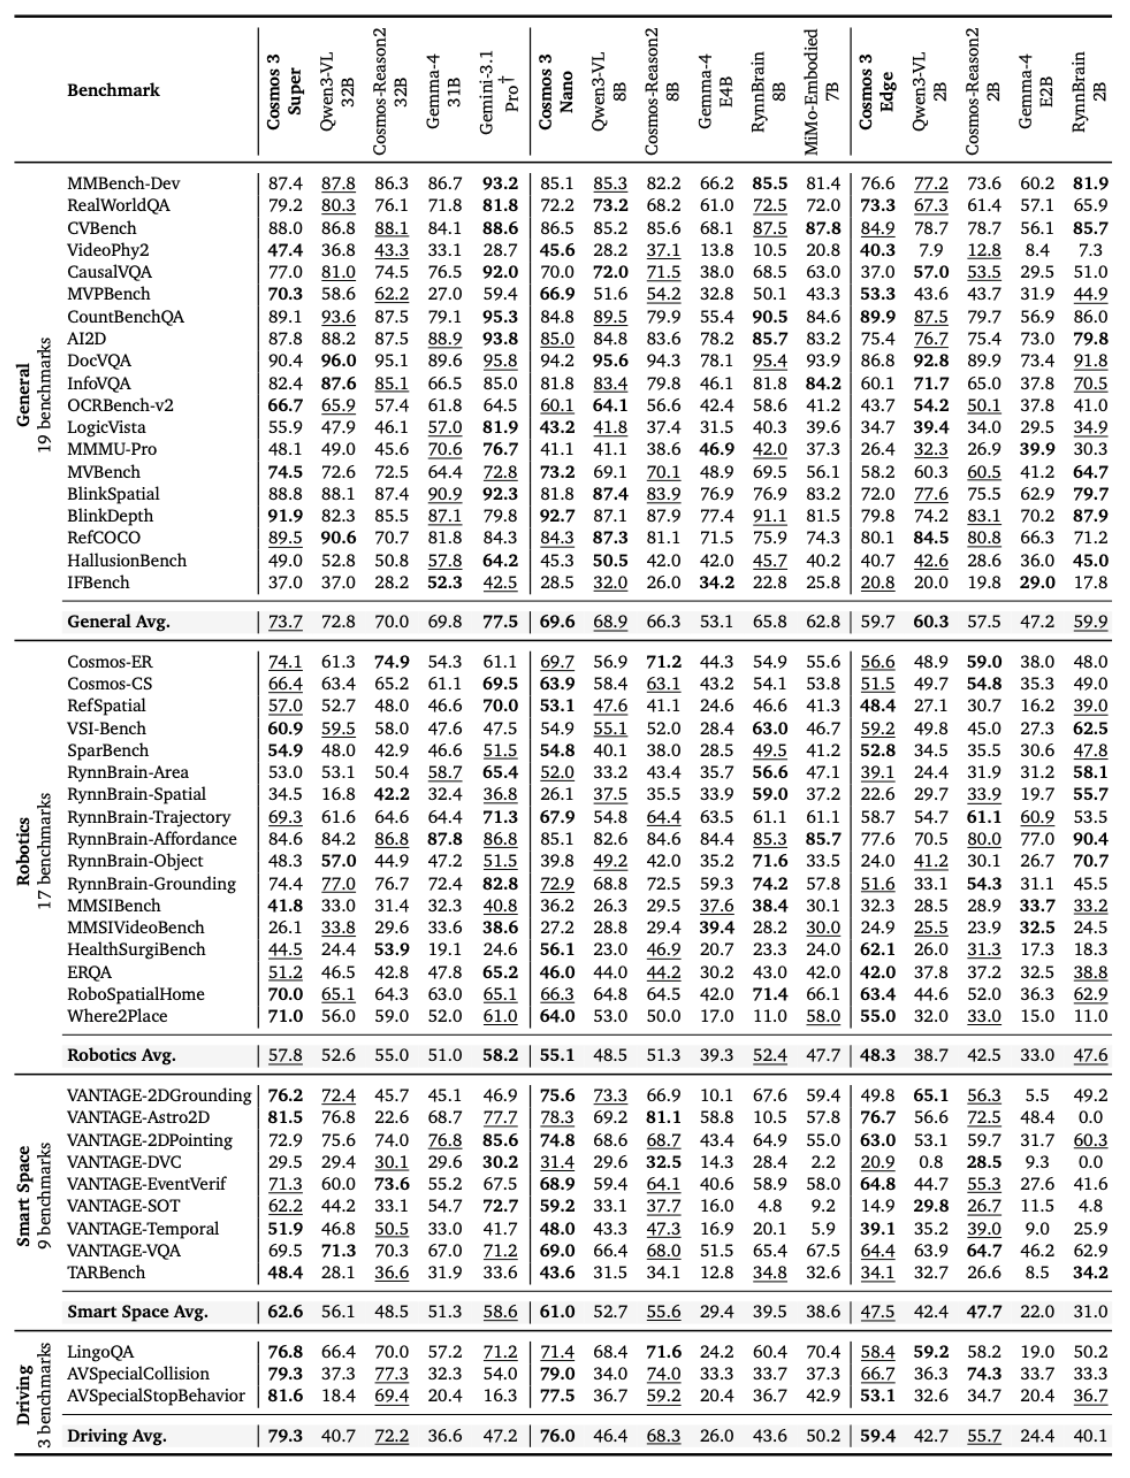
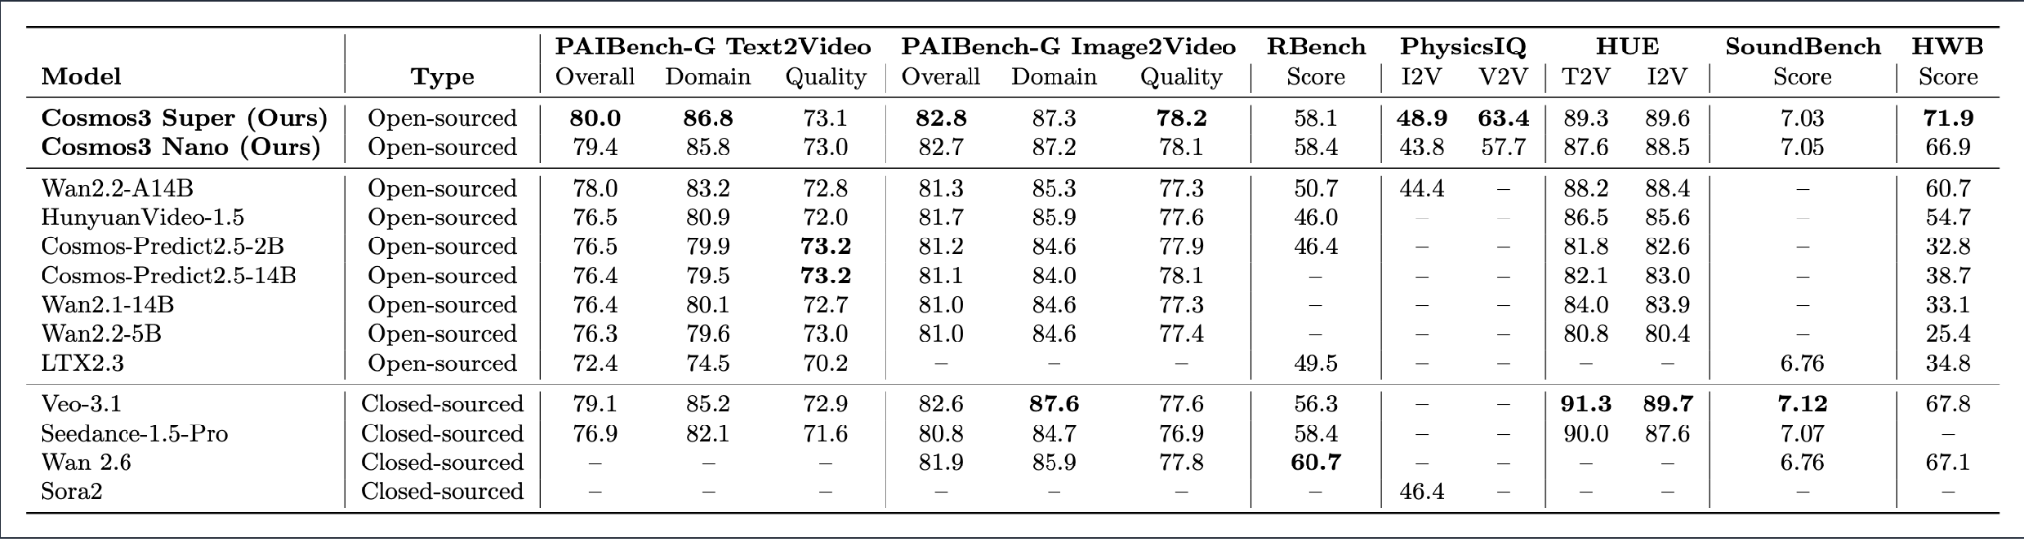
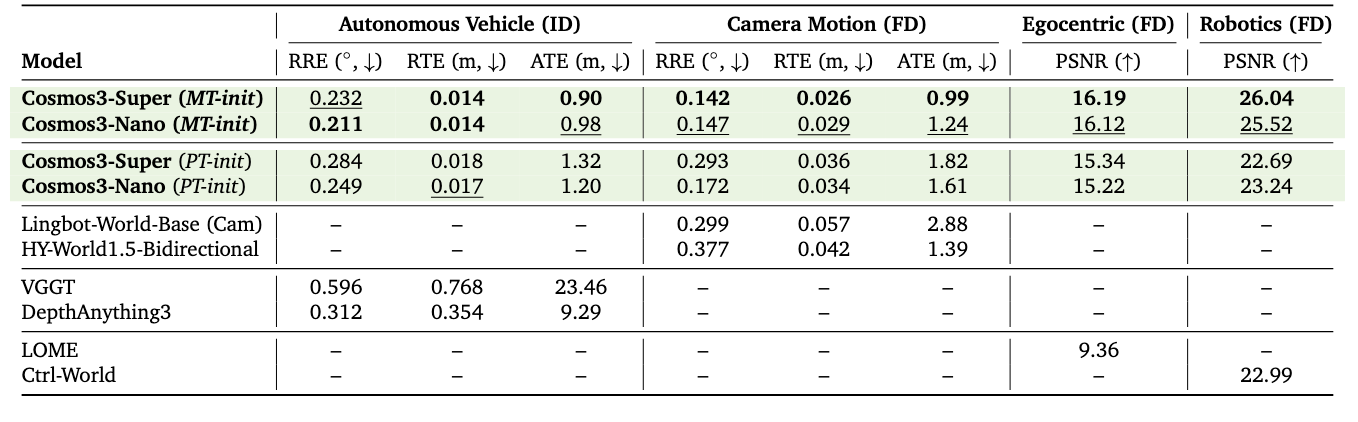
Please see our technical paper for detailed evaluations of the base model.
Overall
Reasoning Benchmarks
Generation Benchmarks
Visual-Audio Generation
Action
System Requirements and Performance
Our Nano model requires a minimum of 60 GB of GPU memory. Our Super model requires a minimum of 145 GB of GPU memory.
This section discusses the optimal configurations and inference runtimes for the Text-to-Video generation task. We discuss both throughput and latency optimized configurations.
We support video generation with different video output specifications. Specifically, we support
- Resolution: 256p, 480p (default), and 720p
- Aspect ratio: 16:9 (default), 4:3, 1:1, 3:4, 9:16
- FPS: 10, 16, 24 (default), 30
- Durations: 5 to 400 frames (default=189 frames)
The performance measurements below use 61 generated frames at 24 FPS, with video resolution set to 720p for Cosmos3-Nano and 480p for Cosmos3-Super, both at a 16:9 aspect ratio.
Usage
- See Cosmos for details.
vLLM-Omni
Container
docker pull vllm/vllm-omni:cosmos3
General Invocation
You can use the release-tested vllm-omni package for deploying an OpenAI-compatible API endpoint:
vllm serve nvidia/Cosmos3-Nano --omni
Setting `--enable-layerwise-offload` can help with memory usage on GPUs with less available memory.
One example of calling this endpoint for text to video generation is:
curl -sS -X POST http://localhost:8000/v1/videos/sync \
  -F "prompt=A small warehouse robot moves a blue box across a clean floor." \
  -F "negative_prompt=blurry, distorted, low quality" \
  -F "size=1280x720" \
  -F "num_frames=81" \
  -F "fps=24" \
  -F "num_inference_steps=35" \
  -F "guidance_scale=4.0" \
  -F "seed=42" \
  -o cosmos3_t2v_output.mp4
Example of sound generation:
curl -sS -X POST http://localhost:8000/v1/videos/sync \
  -F "prompt=A small warehouse robot moves a blue box across a clean floor. Soft motor whirring and gentle wheel hum, with light mechanical clicks as the robot moves." \
  -F "negative_prompt=blurry, distorted, low quality" \
  -F "size=1280x720" \
  -F "num_frames=81" \
  -F "fps=24" \
  -F "generate_sound=true" \
  -F "num_inference_steps=35" \
  -F "guidance_scale=4.0" \
  -F "seed=42" \
  -o cosmos3_t2v_output.mp4
Example of text to image generation:
curl -sS -X POST http://localhost:8091/v1/images/generations \
    -H "Content-Type: application/json" \
    -d '{
      "prompt": "A modern robotics research laboratory, bright lighting, realistic photo",
      "size": "960x960",
      "n": 1,
      "num_inference_steps": 50,
      "guidance_scale": 4.0,
      "flow_shift": 3.0,
      "negative_prompt": "blurry, distorted, low quality",
      "seed": 42
    }' | jq -r '.data[0].b64_json' | base64 -d > cosmos3_t2i.png
Example of action generation:
curl -sS -X POST "http://localhost:8000/v1/videos/sync" \
-F "prompt=Put the pot to the left of the purple item. This video is captured from a first-person perspective looking at the scene." \
 -F "input_reference=@bridge_0_frame0.jpg" \
 -F "size=640x480" \
 -F "num_frames=17" \
 -F "fps=5" \
 -F "num_inference_steps=30" \
 -F "guidance_scale=1.0" \
 -F "flow_shift=5.0" \
 -F 'extra_params={"action_mode":"forward_dynamics","domain_name":"bridge_orig_lerobot","raw_action_dim":10,"action_chunk_size":16,"action_path":"bridge_0.json"}' \
 -F "seed=0"  \
-o cosmos3_forward_dynamics.mp4
vLLM
You can use the release-tested vllm package for deploying an OpenAI-compatible API endpoint:
vllm serve nvidia/Cosmos3-Nano
One example of calling this endpoint is:
curl -s http://localhost:8000/v1/chat/completions \
    -H "Content-Type: application/json" \
    -d '{
      "messages": [
        {
          "role": "user",
          "content": [
            {"type": "image_url", "image_url": {"url": "https://github.com/nvidia-cosmos/cosmos-dependencies/raw/refs/heads/assets/cosmos3/inputs/vision/robot_153.jpg"}},
            {"type": "text", "text": "Caption the image in detail."}
          ]
        }
      ],
      "max_tokens": 4096,
      "seed": 0
    }' | jq -r '.choices[0].message.content'
Diffusers
Cosmos3 is supported in the diffusers package. An example of text to video generation is:
import torch
from diffusers import Cosmos3OmniPipeline
from diffusers.utils import export_to_video

pipe = Cosmos3OmniPipeline.from_pretrained(
    "nvidia/Cosmos3-Nano", torch_dtype=torch.bfloat16, device_map="cuda"
)

prompt = (
    "The video opens with a view of a well-lit indoor space featuring a wooden display case with "
    "compartments filled with various fruits, including bananas, apples, pears, oranges, and carambolas. "
    "The bananas are neatly arranged in the middle compartment, while apples are in the left and a mix "
    "of pears, oranges, and carambolas are in the right. Two robotic arms with grippers are positioned "
    "at the bottom of the frame, with the one on the left remaining stationary, partially obscuring the "
    "apples. The robotic arm on the right begins its action, extending towards the right side of the "
    "display case. It carefully picks up a pear from the fruit section, placing it into a plastic bag "
    "in the shopping cart nearby, which has red handles. After securing the pear, the arm retracts back "
    "to its original position. The process repeats as the robotic arm picks up an orange and places it "
    "in the bag, followed by a carambola. The final frame captures the robotic arm returning to its "
    "initial position, leaving the display case and surrounding area unchanged. The video showcases a "
    "seamless and efficient automated fruit-picking process, highlighting the precision and efficiency "
    "of modern robotics in a retail setting."
)

# Recommended quality-control negative prompt for text-to-video.
negative_prompt = (
    "The video captures a series of frames showing ugly scenes, static with no motion, motion blur, "
    "over-saturation, shaky footage, low resolution, grainy texture, pixelated images, poorly lit areas, "
    "underexposed and overexposed scenes, poor color balance, washed out colors, choppy sequences, jerky "
    "movements, low frame rate, artifacting, color banding, unnatural transitions, outdated special effects, "
    "fake elements, unconvincing visuals, poorly edited content, jump cuts, visual noise, and flickering. "
    "Overall, the video is of poor quality."
)

result = pipe(
    prompt=prompt,
    negative_prompt=negative_prompt,
    num_frames=189,
    height=720,
    width=1280,
    fps=24.0,
)
# macro_block_size=1 allows arbitrary frame sizes (Cosmos3 outputs are not always divisible by 16).
export_to_video(result.video, "cosmos3_t2v.mp4", fps=24, macro_block_size=1)
Limitations
Cosmos3 may produce imperfect outputs in challenging scenarios. Generation artifacts include temporal inconsistency, unstable camera or object motion, imprecise physical interactions, inaccurate audio-video synchronization, and action-state drift — especially in long-horizon or high-resolution outputs. Reasoning may also be incorrect: object states, causal relationships, spatial geometry, temporal ordering, agent intent, and future outcomes can be misinferred, and complex or long-context inputs may yield hallucinated entities, inconsistent interpretations, or implausible predictions. Because the model lacks an explicit physics simulator, 3D geometry, 4D space-time evolution, object permanence, contact dynamics, and physical laws are only approximated — producing artifacts such as disappearing or morphing objects, unrealistic collisions, and physically implausible motions. Quality further degrades in out-of-distribution environments, safety-critical edge cases, and domains underrepresented in training.
Cosmos3 outputs should not be treated as physically accurate simulation, reliable ground-truth reasoning, or safety-certified decision making. Applications involving robotics control, autonomous systems, scientific simulation, or safety-critical planning require additional validation, external constraints, system-level safety analysis, and domain-specific guardrails before deployment.
Inference:
Acceleration Engine: PyTorch, vLLM, vLLM-Omni, Hugging Face Diffusers
Test Hardware: GB200, H100, and A100
Ethical Considerations
NVIDIA believes Trustworthy AI is a shared responsibility and we have established policies and practices to enable development for a wide array of AI applications. Developers should work with their internal model team to ensure this model meets requirements for the relevant industry and use case and addresses unforeseen product misuse.
Please make sure you have proper rights and permissions for all input image and video content; if image or video includes people, personal health information, or intellectual property, the image or video generated will not blur or maintain proportions of image subjects included.
Users are responsible for model inputs and outputs. Users are responsible for ensuring safe integration of this model, including implementing guardrails as well as other safety mechanisms, prior to deployment.
For more detailed information on ethical considerations for this model, please see the Model Card++ Explainability, Bias, Safety & Security, and Privacy subcards. Please report model quality, risk, security vulnerabilities or NVIDIA AI Concerns here.
You are responsible for ensuring that your use of NVIDIA AI Foundation Models complies with all applicable laws..
Get Help
Enterprise Support
Get access to knowledge base articles and support cases or submit a ticket at the NVIDIA AI Enterprise Support Services page..